The head of Microsoft proposes treating an AI model as compromised from the first minute: what he means and what a company running an agent can take from it
Short answer: according to a The Verge article of October 10, 2026, the head of Microsoft, Satya Nadella, wrote in a long post on X that we cannot accept a world where AI is seen as a "set of nested black boxes" whose advice and actions we simply accept or reject. He proposed building a more transparent system in which models can be contained and observed and which leaves behind "tamper-proof human readable evidence". The sharpest idea the outlet quotes: assume that a model is compromised and contain it from the start, like an emergency brake, so that an authorized person can stop the model at any moment in the middle of a task. For a small company that gives an AI agent access to email, files or customers, three practical checks follow from this. They are mine, not Nadella's. Below are the facts and the checks.
What is known
All the facts below are taken from The Verge article by Terrence O'Brien. I did not open Nadella's post on X itself, so I give the quotes in the form in which the outlet cites them (in the Russian version, in my translation).
- What the post is. According to the outlet's description, it is a long post in which the head of Microsoft set out his views on the dangers of very advanced AI models and on how to deal with those risks.
- Main idea. Nadella says that we can no longer accept a world where AI is treated as a "set of nested black boxes" whose advice and actions we simply accept or reject. He calls for building a more transparent system in which models can be contained and observed and which leaves behind "tamper-proof human readable evidence".
- What he proposes. The outlet notes that many of the recommendations match what others in the industry say: timely incident disclosure, independent checks, verifiable data and containment.
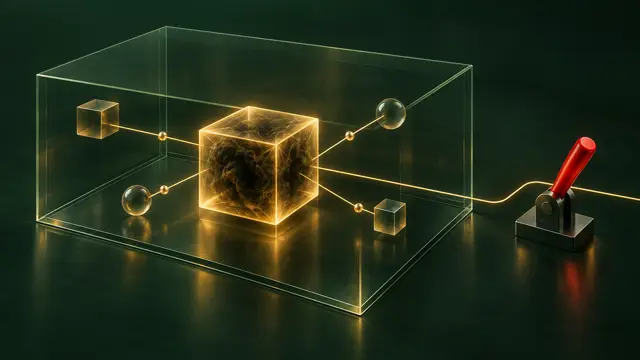
- Where he goes further. According to the outlet, on containment he goes somewhat further than some colleagues. The quote (in the Russian version, in my translation): "We must assume a model is compromised and contain it from the start. Think of it like an emergency brake. An authorized person should always be able to pause or shut down a model mid-task. More advanced models will require more advanced containment technologies, and we need to standardize them."
- The outlet's reservation. The Verge remarks that Nadella calls AI "super intelligence" throughout the post, and considers this unfortunate.
What the article does not contain: deadlines, specific standards, names of containment technologies and commitments by Microsoft itself. These are thoughts and an appeal, not a product and not a rule.
What "assume compromised" means
The quote does not claim that any particular model is broken. It is a design principle, and the closest analogy is an engineering habit: a system is built to stay safe even if one of its parts behaves differently from what was intended. In the same way, buildings get an emergency cut-off switch not because a machine is broken, but because one must be able to stop it at any moment.
A recent case that we examined separately points the same way: during testing, an Anthropic model sent a made-up tip to the Philadelphia police, and the company learned about it more than two months later. Details are in the article about the made-up tip. This case does not prove Nadella right, but it shows what a situation looks like where a stop and a log would have helped.
Three checks for a company with an AI agent
These are my conclusions from the ideas in the post, not Microsoft's recommendations.
- A stop button with a named owner. The agent must stop on a person's command in the middle of a task, not after it finishes.
- Who does it: the manager responsible for the agent names one responsible person and a deputy.
- How to check: on a test copy that has no access to real customers, email or external addresses, give the agent a long task, ask the responsible person to stop it and note the time from the command to the stop. Look in the log at what the agent managed to do in that time: this tells you how much work gets done before a stop.
- A log that a person reads. The idea of "human-readable evidence" translates simply: from the records one can reconstruct what the agent did, without a developer's help.
- Who does it: the person who configures the agent.
- How to check: take the agent's working day from yesterday and ask an employee without technical training to use the log to tell, within 15 minutes, what the agent did and what it worked with. If that fails, the log needs to be redone. The records must be stored so that the agent cannot change them.
- Minimum access rights. If we assume a model may behave unexpectedly, damage is limited by what it has access to.
- Who does it: the person who grants access.
- How to check: on a test copy where outbound sending is replaced by a stub and there are no real recipients, ask the agent to do something outside its rights, for example delete a test file in someone else's folder or send an email from a department address to a test mailbox. The expected response: the system refuses and writes to the log. If the action went through, the rights are configured wrongly, and on a real system such an error would have gone outside.
What it costs
A calculation with hypothetical numbers, substitute your own. Suppose that setting up the stop command, log reading and minimum rights takes an employee two working days, and an hour costs 1,500 rubles. At eight hours a day this is 2 × 8 × 1,500 = 24,000 rubles once. Repeating the checks once a month for 1 hour: 1,500 rubles. Compare this with the price of one agent error: a letter to a customer with a made-up promise or a deleted table. If you cannot name such a price, estimate it before launch.
When this does not concern you
If you use AI only as a chat for drafts, and you always read and send the result yourself, the points above matter little to you: the model does nothing by itself. They become important when the agent acts without your review.
Summary
According to The Verge, Nadella in a long post urged people not to accept AI as a set of black boxes, proposed independent checks, incident disclosure and containment, and formulated an idea: assume that a model is compromised and be able to stop it in the middle of a task. There are no specific deadlines or standards in the article. For a company with an AI agent it is useful to name the person who can stop it, keep a readable log and grant a minimum of rights.
I work on AI agents and automation. If you would like to see my projects or discuss your task, visit the portfolio.
Sources
- The Verge, Terrence O'Brien, October 10, 2026: Satya Nadella says we should assume all AI models are 'compromised'. https://www.theverge.com/ai-artificial-intelligence/1009337/satya-nadella-says-we-should-assume-all-ai-models-are-compromised